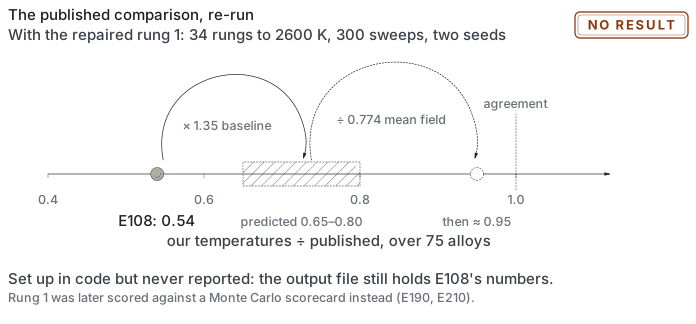
With the heat-capacity reading repaired, do our ordering temperatures now match the published scale?
Not yet. The rerun was set up but no result was ever recorded; the predicted ratio was 0.65 to 0.80, up from 0.54.
In the log: The published comparison, re-run against the repaired rung 1
stoppedDate not stated in the log; it was written between the commit of 2026-09-16 08:54 and the first commit that contains it, 2026-09-16 09:57rung 1 · ordering0 predictions · 0 result paragraphsEXPERIMENTS.md lines 7614–7649
What E127 did and how it came out, drawn from this record and the files it names (book/assets/diagrams/exp/E127.svg).
Results
No result paragraph for this entry was found in the log.
The full record
EXPERIMENTS.md · lines 7614–7649
E127 — The published comparison, re-run against the repaired rung 1
E108 measured rung 1 at 0.54 of the published LTVC scale on 74 of 75 compositions, with
r = +0.439. Four things that produced that number have since changed:
the estimator subtracted a flat median from a curve whose disordered tail falls as A/T^2,
which biased every answer cold (E110). On MoNbTaW the fix alone moved 571 K -> 770 K, a
factor of 1.35;
the reference is mean-field, and Huhn & Widom measured the mean-field-to-Monte-Carlo
factor on this very alloy at 0.774 (E111);
the sampling ran at 90 sweeps per site, which carries a +11 per cent bias no number of
seeds removes (E113);
the ladder stopped too cold for the tail fit to be meaningful.
The script still runs the old settings: np.linspace(200, 2400, 12) - twelve rungs at 200 K
spacing - at 90 sweeps. At twelve rungs the tail_converged guard cannot fire at all, since
it needs at least six rungs in the fitting window and gets four. Raised to 34 rungs from 200
to 2600 K at 300 sweeps, two seeds.
Predicted:
The ratio rises from 0.54 to between 0.65 and 0.80. The estimator repair is worth 1.35
on MoNbTaW, and 0.54 x 1.35 = 0.73. Anything below 0.65 means the repair does not generalise
off MoNbTaW, which would be the more important finding.
The correlation improves on r = +0.439. A cold bias that scaled with temperature was
damaging rank as well as scale, so removing it should help both.
Some of the hottest compositions report tail_converged false. LTVC's table reaches
1760 K; against a ladder ending at 2600 K the fitting window is roughly 1800-2600 K, so a
transition near 1760 sits just below it. Those compositions must be excluded from the
ratio, not averaged in - that is what the guard is for.
After correcting the reference for being mean-field (x 1/0.774), the implied ratio
against a Monte-Carlo-equivalent reference is near 0.95, i.e. rung 1 and the literature
agree to within about five per cent once both corrections are applied.
Falsified if the ratio stays near 0.54, which would mean E110's baseline repair helped
MoNbTaW and nothing else, and the scale error is real and still unexplained.
Related entries
E108 — Rung 1 against 75 published transition temperatures, extracted a week ago and never used