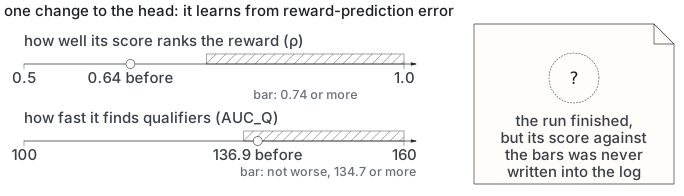
Does a reward-prediction-error learning rule make the brain's score track the reward better?
Not yet. The run finished, but its score against the pre-registered bars was never written into the log.
In the log: E202–E205 — the three fixes, one at a time, then together (2026-09-19 08:47; queued after E201 and E173c)
recordedDate 2026-09-19 08:47, as written in the logrung 1 · ordering0 predictions · 1 result paragraphEXPERIMENTS.md lines 12676–12695, lines 16329–16335
What E204 did and how it came out, drawn from this record and the files it names (book/assets/diagrams/exp/E204.svg).
Results
EXPERIMENTS.md · line 16329
E204 RESULT — the Bennett rule misses its conjunctive bar by 0.01.runs/e204_rpe.log
(finished 2026-09-20 03:00): fly AUC_Q 135.61 ± 17.52, 261 ± 36 distinct finds, best −95,
score–reward ρ +0.73, last window 170. Bars (restated before E202 landed): ρ ≥ 0.74 and
AUC_Q ≥ 134.7. AUC_Q met; ρ rose 0.09 from the 0.64 baseline against the 0.10 required.
Falsified as written, by 0.01 on ρ. E205 then ran as "all three together", the form this log
had called void, without E204 being scored first. Both predate the rung-1 estimator correction
(2026-09-21), so neither is cited for the fly's rung-1 behaviour.
The full record
This entry is written in 2 separate places in the log, shown here in log order.
EXPERIMENTS.md · lines 12676–12695
E202–E205 — the three fixes, one at a time, then together (2026-09-19 08:47; queued after E201 and E173c)
Correction to the E195/E195b tables above: the log's ± is the standard error over seeds
(sd/√n), not the population sd; score_arms.py reports the ddof-1 sd. Baseline = E195b fly:
AUC_Q 73.54 (s.e. 16.25, sd 23), 158 finds (sd 24), last-window finds 123 / 113, mean find
depth −61.9; elitist 88.90 / 169.5 / last-window 147, 139 / depth −74.4 (seed mean).
Code: branch fly-competitive (local search in Forager, imagination + history in
FlyGenerator, prediction_error in mushroom.py, flags + diagnostics in stage_b;
flags off reproduce E195b bit-for-bit by construction and by test). Predictions, each
before its run:
E202 local search (FORAGER_LOCAL_SEARCH=1): last-window finds ≥ 139 (elitist's floor)
and distinct finds ≥ 170; AUC_Q within one seed-sd of elitist. If the last window does
not move, the stall is not the walkers' memory and the anchor mechanism is wrong as built.
E203 imagination (FORAGER_IMAGINE=4): mean find depth deeper by ≥ 5 meV than −61.9;
finds unchanged within sd. Void if E201's score–reward correlation is < 0.2.
E204 RPE (FORAGER_RPE=bennett): score–reward correlation up by ≥ 0.10 over E201's
live arm; AUC_Q not worse.
E205 all three vs elitist, 3 seeds: fly AUC_Q ≥ elitist − one seed-sd, finds ≥
elitist, depth within 5 meV of elitist's. If E205 fails after E202 passed, the pieces
interfere and the combination is retuned one flag at a time, not all together.
EXPERIMENTS.md · lines 16329–16335
E204 RESULT — the Bennett rule misses its conjunctive bar by 0.01.runs/e204_rpe.log
(finished 2026-09-20 03:00): fly AUC_Q 135.61 ± 17.52, 261 ± 36 distinct finds, best −95,
score–reward ρ +0.73, last window 170. Bars (restated before E202 landed): ρ ≥ 0.74 and
AUC_Q ≥ 134.7. AUC_Q met; ρ rose 0.09 from the 0.64 baseline against the 0.10 required.
Falsified as written, by 0.01 on ρ. E205 then ran as "all three together", the form this log
had called void, without E204 being scored first. Both predate the rung-1 estimator correction
(2026-09-21), so neither is cited for the fly's rung-1 behaviour.
Related entries
E202 — E205 — the three fixes, one at a time, then together (2026-09-19 08:47; queued after E201…
E205 — E202–E205 — the three fixes, one at a time, then together (2026-09-19 08:47; queued after…
E201 — does the readout learn the real reward? (2026-09-19 08:12; queued next, operator's call)
E173c — result (2026-09-19 20:23) — the serotonin half of N6, legacy pair
E195 — the fly against the model-free arms on the real reward (2026-09-18 22:58, N1)