Does the search give the same result on the graphics chip as on the processor?
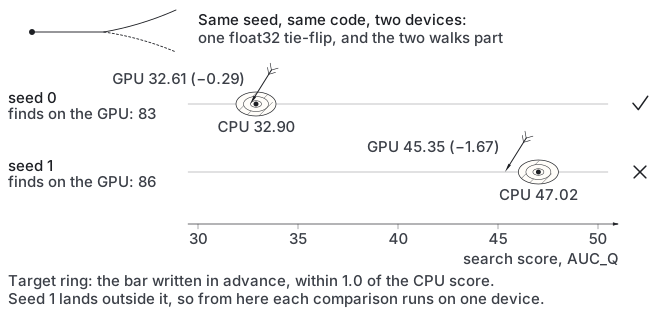
Partly. One run matched within 0.29 points; the other missed the 1.0 bar by 0.67, so each comparison now stays on one device.
In the log: first launch failed at 10:17 — my name collision
falsifiedDate not stated in the log; it was written between the commit of 2026-09-16 19:06 and the first commit that contains it, 2026-09-19 08:35rung 2 · hull, MACE0 predictions · 3 result paragraphsEXPERIMENTS.md lines 11752–11756, lines 11758–11768, lines 11770–11789
What E184b did and how it came out, drawn from this record and the files it names (book/assets/diagrams/exp/E184b.svg).
Results
EXPERIMENTS.md · line 11752
E184b first launch failed at 10:17 — my name collision.FORAGER_DEVICE was already the
MACE calculator's device selector (forager/evaluate/compute.py); setting it to mps made
MACE try to load its float64 checkpoint onto MPS ("MPS framework doesn't support float64").
The brain's selector is renamed FORAGER_BRAIN_DEVICE everywhere (code, tests, chain,
records); the port and its tests are unchanged otherwise. Relaunched.
EXPERIMENTS.md · line 11758
E184b seed 0 — landed at 11:35, 17 min wall for 800 verifications (E171b took ~5 h
per seed on scipy).FORAGER_BRAIN_DEVICE=mps, E171b's protocol, seed 0: AUC_Q 32.61,
83 finds, best −135; fb 595 lessons |Δw| 281 (scipy seed 0: 563, 270); readout DN 5.9% /
LAL 2.2% (6.2 / 2.4). E171b's printed 39.96 ± 7.06 is mean ± standard error over two
seeds, i.e. the seeds were 32.90 and 47.02 (finds 81 and 83); per-seed values were
never written to disk and the printed line does not say which seed was which — a recording
gap, now closed: stage_b writes runs/odt_map/stage_b_<tag>.json with per-seed AUC_Q,
finds, device and seed list. If seed 0 was the 32.90, the prediction (within 1.0, ±2 finds)
is met at 0.29 and +2. Seed 1 on MPS launched to settle the ordering: predicted ≈ 47.0
± 1.0, finds 81 ± 2. The watchdog line at load 22 fired on the chain's tail after the
result had printed and the dump was saved — the run is whole.
EXPERIMENTS.md · line 11770
E184b result (11:56) — prediction FALSIFIED by a small margin; the consequence written in
advance applies. MPS pair vs scipy pair, same seeds, same protocol:
seed   scipy (E171b)   mps (E184b)   ΔAUC_Q   finds scipy → mps
0      32.90 / 81*     32.61 / 83    −0.29    +2
1      47.02 / 83*     45.35 / 86    −1.67    +3
mean   39.96 / 82      38.98 / 84.5  −0.98    +2.5
(* scipy finds 81 and 83; which seed had which is not on disk)
Seed 1 misses the stated bars (|Δ| ≤ 1.0, finds ±2) by 0.67 and 1–3. The two runs are not
the same trajectory: float32 flips rare greedy comparisons in Forager.move and the walk
then diverges (fb lessons 595 vs 563 on seed 0), landing at a statistically equivalent but
not identical outcome — means 1.0 apart against a seed spread of 7. So the pre-registered
rule holds: the device is fixed per experiment family; every within-family comparison runs
on one device; MPS is the device for every new family from here, and no MPS number is set
beside a scipy number as if it were the same run. The per-seed file now written
(runs/odt_map/stage_b_<tag>.json, with device and seeds) makes that auditable.
Wall time: 17 and 18 min per 800 verifications against ~5 h — ×17 end to end (the
remainder is the verifier's icet screen and the learning forward passes on CPU); an MPS
search costs one CPU core.
The full record
This entry is written in 3 separate places in the log, shown here in log order.
EXPERIMENTS.md · lines 11752–11756
E184b first launch failed at 10:17 — my name collision.FORAGER_DEVICE was already the
MACE calculator's device selector (forager/evaluate/compute.py); setting it to mps made
MACE try to load its float64 checkpoint onto MPS ("MPS framework doesn't support float64").
The brain's selector is renamed FORAGER_BRAIN_DEVICE everywhere (code, tests, chain,
records); the port and its tests are unchanged otherwise. Relaunched.
EXPERIMENTS.md · lines 11758–11768
E184b seed 0 — landed at 11:35, 17 min wall for 800 verifications (E171b took ~5 h
per seed on scipy).FORAGER_BRAIN_DEVICE=mps, E171b's protocol, seed 0: AUC_Q 32.61,
83 finds, best −135; fb 595 lessons |Δw| 281 (scipy seed 0: 563, 270); readout DN 5.9% /
LAL 2.2% (6.2 / 2.4). E171b's printed 39.96 ± 7.06 is mean ± standard error over two
seeds, i.e. the seeds were 32.90 and 47.02 (finds 81 and 83); per-seed values were
never written to disk and the printed line does not say which seed was which — a recording
gap, now closed: stage_b writes runs/odt_map/stage_b_<tag>.json with per-seed AUC_Q,
finds, device and seed list. If seed 0 was the 32.90, the prediction (within 1.0, ±2 finds)
is met at 0.29 and +2. Seed 1 on MPS launched to settle the ordering: predicted ≈ 47.0
± 1.0, finds 81 ± 2. The watchdog line at load 22 fired on the chain's tail after the
result had printed and the dump was saved — the run is whole.
EXPERIMENTS.md · lines 11770–11789
E184b result (11:56) — prediction FALSIFIED by a small margin; the consequence written in
advance applies. MPS pair vs scipy pair, same seeds, same protocol:
seed   scipy (E171b)   mps (E184b)   ΔAUC_Q   finds scipy → mps
0      32.90 / 81*     32.61 / 83    −0.29    +2
1      47.02 / 83*     45.35 / 86    −1.67    +3
mean   39.96 / 82      38.98 / 84.5  −0.98    +2.5
(* scipy finds 81 and 83; which seed had which is not on disk)
Seed 1 misses the stated bars (|Δ| ≤ 1.0, finds ±2) by 0.67 and 1–3. The two runs are not
the same trajectory: float32 flips rare greedy comparisons in Forager.move and the walk
then diverges (fb lessons 595 vs 563 on seed 0), landing at a statistically equivalent but
not identical outcome — means 1.0 apart against a seed spread of 7. So the pre-registered
rule holds: the device is fixed per experiment family; every within-family comparison runs
on one device; MPS is the device for every new family from here, and no MPS number is set
beside a scipy number as if it were the same run. The per-seed file now written
(runs/odt_map/stage_b_<tag>.json, with device and seeds) makes that auditable.
Wall time: 17 and 18 min per 800 verifications against ~5 h — ×17 end to end (the
remainder is the verifier's icet screen and the learning forward passes on CPU); an MPS
search costs one CPU core.