With lessons switched on, do the whole-brain walkers climb higher?
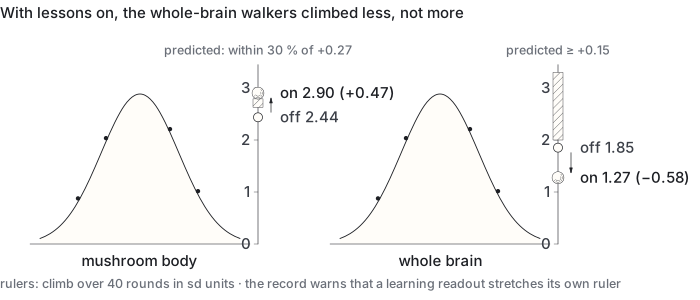
No. Their climb fell by 0.58 standard deviations with lessons on, and the record warns that a learning readout stretches its own ruler.
In the log: E155's walk statistics, re-run under the learned LAL + DNa + MBON readout
falsifiedDate not stated in the log; it was written between the commit of 2026-09-16 19:06 and the first commit that contains it, 2026-09-19 08:35rung 0 · energy model0 predictions · 1 result paragraphEXPERIMENTS.md lines 10424–10450, lines 10482–10514
What E160 did and how it came out, drawn from this record and the files it names (book/assets/diagrams/exp/E160.svg).
Results
EXPERIMENTS.md · line 10482
E160 result — falsified on three of four, and the pre-registered branch opens.
Prediction 1 falsified: the whole brain's learning contribution is −0.58 sd, not
≥ +0.15 — with lessons on, the walkers climb less than with them off. Prediction 2
falsified: relocations moved away from parity (x1.49 → x1.78). Prediction 3 falsified in
the other direction: the mushroom body's contribution rose to +0.47, outside the ±30% I
allowed around E155's +0.27. Prediction 4 confirmed: acceptance x0.93, scale-free as
ever. The learning-off passes reproduce E155 to every digit, as the identity test in
tests/test_readout.py says they must.
The branch that opens is the one I pre-registered:E159's 17x did not come from lessons
steering the whole-brain walk better, at least not inside forty rounds. Before reading more
into the sign, one caveat against my own instrument: score_rise_sd divides the walkers'
mean score by a landscape sd measured before any lesson, and a learned readout rescales
the score as |w| grows, so climb "in sd units" is not scale-free under this readout — the
mushroom body's jump from +0.27 to +0.47 with no other change is the same warning. Two
readings survive it: (i) the readout's gain lives in which proposals are chosen for
verification (the round's top four), not in how far walkers climb; (ii) forty rounds is
too few — E159 ran two hundred, and the first two lessons teach nothing (E159's unit-test
observation). Neither is separable with this metric.
Next measurement, scale-free: the same four passes, recording per round the ladder's
own rung-0 verdict (Verifier.screen p) at every walker's position — where the swarm
actually stands, in the units the search is paid in — instead of the circuit's score.
Prediction goes in before it runs. E161's saved readout (running) decides the other half:
whether LAL/DNa took weight at all.
The full record
This entry is written in 2 separate places in the log, shown here in log order.
EXPERIMENTS.md · lines 10424–10450
E160 — E155's walk statistics, re-run under the learned LAL + DNa + MBON readout
E155 measured the walk under the MBON compartment readout: the whole-brain walkers accepted
as often (x0.95) but relocated half again as much (x1.49), climbed a quarter less (x0.76),
and forty rounds of lessons moved their climb by +0.03 sd against +0.27 on the mushroom
body. E159 then changed one thing — the readout — and the whole brain went from 0.15 to 2.61
AUC_Q. This asks which of E155's numbers the readout changed. Same protocol: 12 elements,
24 walkers x 10 moves x 40 rounds, step 0.05, lr 0.1, seed 0, learning off then on with the
rung-0 reward; FORAGER_READOUT's construction applied inside the script.
Predicted:
The learning contribution on the whole brain rises from +0.03 sd to at least +0.15,
i.e. more than half of the mushroom body's +0.27 — lessons now reach the readout that
steers the walk, which is what E159's 17x says must have happened.
Relocations on the whole brain fall from x1.49 toward parity (below x1.2): the
learned readout smooths the landscape's gradient direction where the fixed compartment
readout, fed by a shortcut it could not weigh, made headings fail.
The mushroom body's learning contribution is within 30% of E155's +0.27 under its
learned MBON readout — the control moves little, matching E159's 1.48 → 2.06 inside error.
Acceptance stays within 20% on both, as before; greedy acceptance is scale-free.
Falsified if the whole-brain learning contribution stays below +0.08 sd — then E159's
gain came from the starting landscape the learned readout produces (the initial MBON
valences read alongside silent LAL/DNa nodes), not from lessons, and the mechanism is a
better prior rather than better learning; that would send the next hour to saving and
reading the readout weights rather than to step 2b.
EXPERIMENTS.md · lines 10482–10514
E160 result — falsified on three of four, and the pre-registered branch opens.
Prediction 1 falsified: the whole brain's learning contribution is −0.58 sd, not
≥ +0.15 — with lessons on, the walkers climb less than with them off. Prediction 2
falsified: relocations moved away from parity (x1.49 → x1.78). Prediction 3 falsified in
the other direction: the mushroom body's contribution rose to +0.47, outside the ±30% I
allowed around E155's +0.27. Prediction 4 confirmed: acceptance x0.93, scale-free as
ever. The learning-off passes reproduce E155 to every digit, as the identity test in
tests/test_readout.py says they must.
The branch that opens is the one I pre-registered:E159's 17x did not come from lessons
steering the whole-brain walk better, at least not inside forty rounds. Before reading more
into the sign, one caveat against my own instrument: score_rise_sd divides the walkers'
mean score by a landscape sd measured before any lesson, and a learned readout rescales
the score as |w| grows, so climb "in sd units" is not scale-free under this readout — the
mushroom body's jump from +0.27 to +0.47 with no other change is the same warning. Two
readings survive it: (i) the readout's gain lives in which proposals are chosen for
verification (the round's top four), not in how far walkers climb; (ii) forty rounds is
too few — E159 ran two hundred, and the first two lessons teach nothing (E159's unit-test
observation). Neither is separable with this metric.
Next measurement, scale-free: the same four passes, recording per round the ladder's
own rung-0 verdict (Verifier.screen p) at every walker's position — where the swarm
actually stands, in the units the search is paid in — instead of the circuit's score.
Prediction goes in before it runs. E161's saved readout (running) decides the other half:
whether LAL/DNa took weight at all.
Related entries
E155 — The walk's own statistics on the two landscapes
E159 — Task 0, step 2: read the brain at LAL + DNa, not only at the 97 MBONs
E161 — Where the learned readout puts its weight (E159's unmeasured prediction 2)